A major incident in a regulated firm starts two clocks. The first is the technical one, which begins when engineering opens an investigation. The second is the regulatory one, which started earlier, when the service first degraded.
Consider a payments provider whose settlement platform slows at 09:40 on a Thursday. Not down, slow. Queues build behind it while the service desk logs latency alerts against a database that looks healthy on every dashboard anyone has open.
The people working it have immediate questions. Is this affecting one customer or all of them? Is the service degraded or simply slower than usual? Does this count as an important business service being disrupted? Who decides that? And has anyone started the clock?
This is where operational resilience during a live incident becomes a different thing from operational resilience on paper. The service map and the impact tolerances were signed off months ago. What matters at 09:55 is whether anyone can act on them.
Impact tolerance is measured in elapsed time, and elapsed time does not wait for a decision.
What Is Operational Resilience During A Live Incident?
Operational resilience during a live incident is a firm’s ability to keep an important business service running, or restore it inside its agreed impact tolerance, while the disruption is still unfolding. It is distinct from resilience planning, which is the mapping and tolerance-setting done in advance.
The plan defines what is being protected and for how long. The live response determines whether it actually was. Most firms in scope have completed the first. The second is only ever tested on the day.
What Does The Regulator Actually Require?
The FCA’s operational resilience rules ask firms to do three things. Identify the important business services that could cause intolerable harm to consumers or markets if disrupted. Set an impact tolerance for each. Then be able to stay inside that tolerance when something goes wrong.
The rules came into force on 31 March 2022, and firms had until 31 March 2025 to show they could operate their important business services within their impact tolerances. They sit in the FCA Handbook at SYSC15A and originate in policy statement PS21/3. The Prudential Regulation Authority sets out parallel expectations in SS1/21 on impact tolerances.
Firms with EU operations carry a second obligation. DORA, Regulation (EU) 2022/2554, entered into application on 17 January 2025 and requires major ICT-related incidents to be reported to competent authorities. Accurate reporting depends on knowing when an incident started, what it affected and what was done about it, which makes it a live-incident problem before it is ever a reporting one.
The first two requirements are mapping exercises with a deadline. The third has no deadline, because it is tested whenever something breaks.
Why The Tolerance Clock Starts Before Anyone Declares
A four-hour impact tolerance does not begin when the incident is declared. It begins when the service degrades. That distinction sounds academic until a firm measures the gap between the two on a real incident.
In the payments example the clock started at 09:40. If nobody says the words “important business service” until 10:15, thirty-five minutes of a four-hour budget has gone before anyone with the authority to invoke a workaround knew there was a decision to make.
That time is rarely recovered later. Workarounds take time to invoke. Client communications take time to approve. The minutes lost at the start are the cheapest minutes in the whole incident and the ones most often spent without anyone noticing.
Detection Is Not The Same As Declaration
Monitoring told the service desk something was slow at 09:40. That is detection. Declaration is a separate act, and in most firms it depends on a person deciding the situation is serious enough to say so out loud.
Declaring a major incident in a regulated firm has consequences, and the person on shift knows all of them:
- Senior people are pulled in, sometimes out of hours
- Client communications may be triggered before the cause is known
- A formal record starts, and it will be read later by people who were not there
- The declaration is difficult to walk back if the issue turns out to be minor
In the absence of a written threshold, that combination produces hesitation. The engineer weighs a possible false alarm against a possible delay, alone, at speed, without knowing how much of the tolerance has already gone.
Hesitation is the most expensive thing in the first hour and the hardest to see afterwards, because it leaves no artefact. A post-incident review can show when the incident was declared. It cannot easily show the twenty minutes somebody spent deciding whether to.
Teams Are Rewarded For Fixing, Not For Escalating
Technical teams are measured on resolution. The instinct when something looks odd is to investigate first and escalate once there is something worth escalating. That instinct is reasonable, professional, and expensive under an impact tolerance regime.
Thirty minutes of quiet diagnosis is thirty minutes of the tolerance, spent to avoid raising a false alarm. The cost of the false alarm is an awkward conversation. The cost of the delay is regulatory. Most firms have never made that trade-off explicit, so individual engineers make it alone, at speed, without knowing the budget they are spending.
Leadership Needs A Different Picture From Engineering
An engineering lead needs to know which node is failing and what changed recently. A COO needs to know something else entirely, and the two questions rarely get answered by the same status update.
At 10:05 in the payments incident, leadership needs four answers:
- Which important business service is affected, in the words used on the service map
- How much of its impact tolerance has been consumed so far
- Whether a workaround exists and who has the authority to invoke it
- What clients have been told, and by whom
None of those is a technical question. All four are usually answered by assembling information from a monitoring tool, a chat channel, a service management ticket and two people’s recollection. That assembly is the delay.
Where Do Plans And First Hours Diverge?
A resilience plan is written in the calm and executed in the noise. The plan assumes a set of conditions that the first hour of a real incident rarely supplies, and the gap between the two is where tolerance gets spent.
What the plan assumes | What the first hour usually delivers |
The incident has been declared | Three teams are working it and nobody has declared anything |
Roles are assigned and understood | People are helping wherever they can see a problem |
Leadership has one agreed status | Leadership has two updates that disagree |
The tolerance clock started at detection | Nobody agrees when the clock started |
Actions are tracked to completion | Actions were mentioned on a call and assumed |
None of those gaps is a failure of competence. Each is a failure of structure, and a plan document cannot supply structure on its own.
Challenging The Assumption That A Completed Programme Means Resilience
Most firms that lose control during an incident have an adequate plan, a current service map and tolerances the board has approved. The programme was delivered. The deadline was met. The assumption that follows is that the firm is therefore resilient.
The assumption holds for everything a regulator asks in writing. It holds for very little of what a duty manager needs on a Thursday morning.
Service mapping done to satisfy a deadline tends to stop at the level the deadline required. It names the service, the tolerance and the dependencies. It does not usually say who declares, what thresholds trigger a declaration, or how a degradation in a supporting system becomes a recognised service impact. Those are operational questions and the mapping exercise rarely reaches them.
That is the honest position many firms are in eighteen months after the deadline. The documentation is complete and defensible. The operational layer underneath it was never built, because nothing in the programme required it.
A Practical Test For Operational Resilience
Take one important business service from the map. Pick a plausible degradation, not an outage. Then ask the people who would actually be on shift how the firm would establish, within ten minutes, that the tolerance clock had started.
The useful questions are narrow:
- Who is permitted to declare that this service is impaired, and who deputises out of hours
- What threshold triggers that declaration, written down, not judged in the moment
- How the person on shift would know the tolerance had started rather than assuming it starts at declaration
- Where leadership would read a single current status instead of two conflicting updates
- How an action assigned on a call is confirmed as done rather than assumed
If the answer to the first question depends on one person noticing and choosing to speak up, the resilience exists on paper and nowhere else. That is worth knowing before the next incident rather than during it.
How Crises Control Supports Incident Coordination
Crises Control provides the coordination layer between detection and response. Most tools in this space solve one part of the problem. Alerting platforms reach people quickly and stop at the message. Planning and governance platforms hold the policy and the service map without being built for real-time response. Everyday tools such as Teams carry the conversation and leave no structured record of who decided what.
Most competitors either notify people or document plans. Crises Control executes the response. Built for real incidents, not demos.
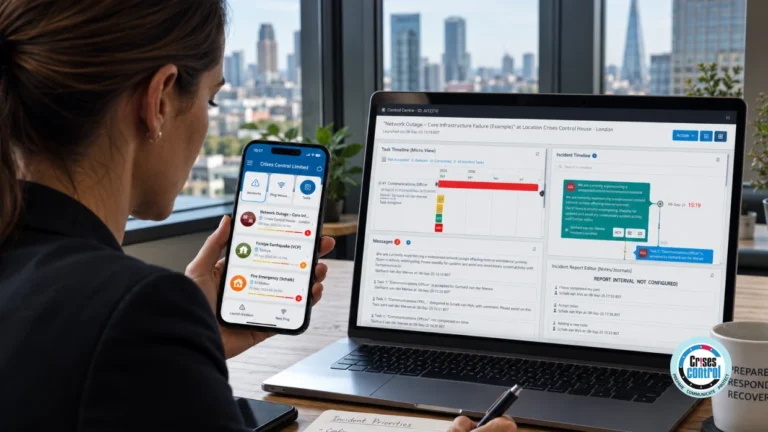
In practice that means declaration becomes a structured action rather than a judgement call in a chat thread. Incident management software activates a defined response against the affected service, assigns roles, starts the timeline automatically and records communications and decisions as they happen. Response teams can reach it remotely, which matters when the incident involves the firm’s own systems.
The same record does a second job afterwards. A timeline captured live is a defensible account of what happened. A timeline assembled from memory and chat exports a week later is an argument. That is where operational resilience for financial services stops being a mapping exercise and becomes demonstrable, and it is the same evidence a DORA report depends on.
Assigning a workaround on a call and assuming it happened is the most common gap in the first hour. Tracking it through incident task management gives it an owner and a visible status. See Crises Control’s business continuity software page for how response plans connect to the wider continuity arrangements.
The platform does not decide whether a service has breached its tolerance. That remains a human judgement made against a written threshold. Its role is to make sure the judgement is made by the right person, at the right moment, with the right information in front of them.
Resilience Is What Happens In The First Hour
Mapping tells a firm what it is protecting and how long it has. Coordination is what turns that into control on the day. The operational record is what turns control into proof afterwards.
Most firms in scope have the first. The work worth doing now is the layer underneath it, starting with the gap between detection and declaration, because it is the cheapest time to recover and the least visible on any dashboard. To see how structured incident coordination works against your own important business services, request a walkthrough with the Crises Control team.
Frequently Asked Questions
What is operational resilience during a live incident?
It is a firm’s ability to keep an important business service running, or restore it inside its agreed impact tolerance, while the disruption is still happening. This is distinct from resilience planning, which is the mapping and tolerance-setting done in advance. The plan defines what is being protected. The live response determines whether it actually was.
When does the impact tolerance clock start?
The clock starts when the important business service degrades, not when the incident is declared. Any time spent diagnosing before escalation is already being spent inside the tolerance. Firms that treat declaration as the start point routinely underestimate how much of the budget has gone.
What did the FCA require and by when?
The FCA’s operational resilience rules came into force on 31 March 2022, requiring firms to identify important business services and set impact tolerances for each. Firms then had until 31 March 2025 to be able to operate those services within their tolerances. The rules sit in the FCA Handbook at SYSC15A.
How does DORA affect incident response for financial firms?
DORA, Regulation (EU) 2022/2554, entered into application on 17 January 2025 and requires major ICT-related incidents to be reported to competent authorities. Accurate reporting depends on knowing when an incident started, what it affected and what was done. That makes the reporting obligation something met during the incident rather than after it.
Does incident coordination software replace a business continuity plan?
No. A continuity plan defines what a firm protects and what good looks like, and it remains necessary. Coordination software is the operational layer that executes it, assigning roles, tracking actions and recording decisions as they happen. Operational resilience during a live incident depends on both.
This article was drafted with AI assistance and reviewed by the Crises Control team. Featured image: AI-generated.