Most IT teams already have a way to identify technical problems. Monitoring tools detect unusual activity, service management systems record incidents and alerting tools notify the people responsible for investigating them.
The difficulty often begins after the notification has been sent.
A serious IT incident can require decisions from people who are not involved in the technical investigation. Customer support may need to explain service interruptions. Operations may need to activate a workaround. Legal may need to assess contractual responsibilities. Senior leadership may need to decide which services should be prioritised while IT works towards recovery.
These activities cannot be managed effectively through a collection of disconnected messages, informal conversations and separate spreadsheets. The organisation may know that something is wrong without having a clear view of its overall impact, who owns each action or when a decision needs to be escalated.
This is where the difference between IT alerting and incident coordination becomes clear. Alerting draws attention to a problem. Coordination brings the right people together, establishes responsibilities, manages communication and connects technical recovery with the needs of the wider business.
An Incident Management Platform can support this process by linking response plans, role-based communication, task ownership, escalation and incident records. It does not replace monitoring or technical investigation. It helps ensure that an alert becomes an organised action rather than another message waiting for someone to respond.
What Is The Difference Between IT Alerting And Incident Coordination?
An Incident Management Platform is a digital system that connects incident detection with communication, decision-making, task ownership, escalation, recovery and incident records. It helps IT teams manage the wider organisational response instead of relying on alerts, email threads and spreadsheets alone.
IT alerting is designed to make sure the right person knows that something has happened. It may notify an engineer when a server fails, a service becomes unavailable or a performance threshold is breached.
Incident coordination begins after that initial notification. It asks what needs to happen next, who needs to be involved, which decisions are required and how the response will be tracked.
The difference can be summarised as follows:
- Detection identifies a possible problem.
- Alerting notifies a person or team.
- Incident management establishes the response.
- Incident coordination connects people, decisions, actions and communication.
- Recovery restores services and confirms that the organisation can operate normally.
- Review identifies what needs to change before the next incident.
These activities support one another, but they are not interchangeable.
IT Alerting Software may be effective at sending notifications to technical responders. It may also include on-call schedules, escalation rules and acknowledgement tracking. Those functions are useful, but they do not always provide a complete view of the wider response.
A serious incident needs more than a message stating that a system is unavailable. It needs a structure for managing the consequences.
Why The Initial Alert Is Only The Starting Point
The first alert usually contains limited information. It may identify the affected system, the time of the event and the type of technical failure. It may not explain which business services are affected, whether customers are experiencing disruption or whether the incident requires executive involvement.
This creates pressure for IT teams because they must investigate the technical cause while responding to questions from other departments.
For example, a failed database may affect:
- Customer-facing applications
- Payment processing
- Internal reporting
- Staff access to business systems
- Supplier transactions
- Customer support operations
- Contractual commitments
- Business continuity arrangements
The technical team may be focused on restoring the database. Other departments need to understand what failure means for their own responsibilities.
Without a coordinated process, each team may create its own version of the incident. Customer support may tell users that service will return shortly, while engineering has no reliable recovery estimate. Sales may continue scheduling customer demonstrations without knowing that the platform is unavailable. Executives may receive separate updates from several people, each containing different information.
The technical response may be progressing, but the business response is becoming fragmented.
A Shared Incident Picture Reduces Confusion
One of the first responsibilities of an incident manager is to establish a shared picture of the situation.
This does not mean collecting every technical detail and sending it to everyone. It means creating a reliable record that explains what is known, what is suspected, what is affected and what needs to happen next.
A useful incident record should include:
- Confirmed facts: Information supported by evidence.
- Working assumptions: Issues that still need investigation.
- Affected services: The business services, systems or locations experiencing disruption.
- Current impact: What employees, customers, suppliers or partners are experiencing.
- Actions completed: Steps already taken by technical and business teams.
- Open actions: Tasks that still need to be completed.
- Decisions required: Choices that need approval from an appropriate person.
- Next update: When stakeholders can expect further information.
This structure helps separate evidence from speculation. It also gives decision-makers enough context without requiring them to interpret technical logs or follow several message threads.
A shared picture becomes especially useful when teams are working across different locations or time zones. Clear timestamps, named owners and consistent updates make handovers easier and reduce the risk of two teams acting on different information.
The record should also remain useful after the incident. A clear timeline can help the organisation understand when the issue began, which decisions were made, how the response developed and where delays occurred.
Business Impact Must Be Considered Alongside The Technical Problem
A common mistake is to classify an incident only by its technical severity.
A system failure affecting one internal application may be technically serious but have limited business impact. A smaller issue affecting a customer-facing payment service may require a much wider response because it prevents customers from completing important activities.
Incident classification should therefore consider both the technical condition and the services connected to it.
Technical Questions
- Which systems or applications are affected?
- Is the problem limited to one environment?
- Are other systems showing related symptoms?
- Is data integrity at risk?
- Is there a security concern?
- Can the technical team estimate recovery time?
- Are normal monitoring and communication tools still available?
Business Questions
- Which critical services are unavailable?
- Are customers unable to complete important activities?
- Are employees unable to perform essential work?
- Are suppliers or partners affected?
- Could contractual commitments be missed?
- Is there a financial, legal or regulatory concern?
- Does the organisation need to activate business continuity arrangements?
- Which decisions cannot wait for full technical recovery?
These questions help determine whether an incident should remain within IT or move to a wider response structure.
They also help prevent a narrow technical view from delaying action elsewhere in the business. A service may be technically recoverable, but the organisation may still need to manage customer communication, temporary workarounds, supplier contact or operational restrictions.
Role-Based Response Prevents Unclear Ownership
During a serious IT incident, several people may be involved without having the same responsibilities.
The CIO may need to approve major business decisions. The IT Operations Director may coordinate technical recovery. The Service Delivery Director may manage customer and service commitments. The CISO may assess security implications. The Business Continuity Manager may coordinate workarounds and continuity arrangements. Communications may prepare internal or external updates.
If these roles are not defined in advance, people may assume that someone else is handling an important task.
A role-based response should make clear:
- Who can declare or activate an incident
- Who coordinates the overall response
- Who leads the technical investigation
- Who assesses business impact
- Who approves customer communications
- Who contacts suppliers or external partners
- Who authorises service workarounds
- Who escalates unresolved issues
- Who can act when the usual decision-maker is unavailable
The exact structure will differ between organisations. The principle remains the same: every important responsibility should have a clear owner.
An incident management platform for IT teams should connect incident types to defined roles, response plans and escalation routes. It should also account for deputies and delegated authority. A process that depends on one person being available is difficult to rely on during a serious incident.
Communication Needs A Structure, Not Just A Channel
Many organisations already have several communication channels. They may use email for formal updates, Microsoft Teams for discussion, SMS for urgent messages and phone calls for senior leaders.
The problem is not always a lack of channels. It is the absence of a clear communication process.
During an incident, people need to know:
- Which channel contains the official update
- Who is responsible for issuing information
- Which audiences need to be contacted
- What information has been confirmed
- What employees or customers should do
- When the next update will be shared
- Where urgent questions should be directed
Different audiences need different messages.
Technical teams may need detailed information about affected infrastructure, logs and recovery steps. Employees may need practical guidance about system access. Customer support may need an approved explanation. Senior leaders may need a summary of impact, decisions and risks.
Mass Notification Software for IT Teams can support urgent communication when employees, service owners, suppliers or senior leaders need clear instructions during a major disruption. The value comes from using communication as part of a response process, rather than treating every message as a separate activity.
The goal is not to send every update to everyone. It is to provide the right information to the people who need it to make a decision or take action.
Tasks Need Owners, Deadlines And Escalation
A coordinated response involves more than sending messages. It requires work to be completed across several teams.
During a network outage, tasks may include confirming the affected infrastructure, checking whether backup connectivity is available, assessing customer impact, contacting an external service provider, preparing a customer support response and reviewing continuity workarounds.
A task list is only useful when each task has a named owner and a clear status.
A practical task record should show:
- The action required
- The reason for the action
- The responsible person
- The supporting team
- The priority
- The deadline or review time
- The current status
- Any blocker or dependency
- The escalation route if the task is not completed
This allows the incident manager to identify delays before they become larger problems.
It also gives leadership a more useful view of progress. Instead of asking whether the incident is under control, leaders can see which actions are complete, which are delayed and which decisions are preventing progress.
Why Email, Messaging Apps And Spreadsheets Can Break Down
Email, messaging apps and spreadsheets are familiar, accessible and useful for everyday work. They can also support smaller incidents when only a few people are involved.
The difficulty comes when the incident becomes complex.
Information can become spread across several inboxes, chat channels and documents. Different teams may update separate task lists. A decision may be recorded in a private message rather than in the main incident record. Someone may be working from an old version of the plan without realising that the situation has changed.
Manual processes can also depend on one person’s knowledge. If the person maintaining the spreadsheet becomes unavailable, the rest of the response team may struggle to understand the current position.
There is also a risk of confusing discussion with action. Several people may talk about contacting a supplier, preparing a customer message or checking a backup system, but nobody may be clearly responsible for completing the task.
Digital coordination does not remove the need for judgement. It gives the organisation a more consistent way to keep information, responsibilities, actions and decisions connected.
Challenging The Assumption That More Alerts Mean Better Preparedness
It is easy to assume that an organisation is well prepared because it receives alerts quickly.
Fast notification is useful, but a large volume of alerts can create its own problems. If every event receives the same level of attention, responders may struggle to identify which issues require wider involvement.
Alert fatigue can also affect human judgement. People may begin treating notifications as routine, ignore repeated messages or assume that another team is already dealing with the issue.
The National Cyber Security Centre’s guidance on responding to disruptive cyber incidents also emphasises the need for organisations to prepare for disruption, establish responsibilities and coordinate their response.
Preparedness should therefore be assessed through practical questions:
- Can the organisation identify which alerts require a coordinated response?
- Can the right people be contacted outside normal working hours?
- Can the response be activated if email or internal systems are unavailable?
- Does everyone know who owns the incident?
- Can teams share one reliable view of the situation?
- Are business and customer impact assessed early?
- Are tasks assigned and escalated when necessary?
- Can the organisation record decisions for later review?
The objective is not to create more alerts. It is to turn important alerts into clear, managed action.
A Practical Decision Framework For IT Leaders
CIOs, IT Operations Directors and Business Continuity Managers can use the following framework to assess whether their current approach goes beyond alerting.
Step 1: Identify The Signal
Establish what triggered the response. This could be a monitoring alert, user report, service desk ticket, supplier notification or security event. Record the source, time and initial details.
Step 2: Validate The Incident
Confirm whether the issue is genuine and identify the affected system, service or location. Avoid escalating every isolated alert before there is enough information to justify a wider response.
Step 3: Assess Business Impact
Consider customer access, employee productivity, financial activity, suppliers, contractual obligations and critical services. Ask which activities may be affected if recovery takes longer than expected.
Step 4: Select The Response Level
Decide whether the issue can remain with the technical team or whether wider business functions need to be involved. Use agreed criteria so the decision does not depend entirely on personal judgement.
Step 5: Activate The Response Plan
Contact the required roles, confirm responsibilities and establish the communication process. Make sure deputies or alternative contacts are included if the usual responders are unavailable.
Step 6: Create A Shared Incident Record
Capture facts, assumptions, impact, decisions, tasks, updates and the next review point. Keep the record accessible to authorised people who need it to make decisions or complete actions.
Step 7: Coordinate Parallel Work
Assign tasks to technical and business owners. Track progress, dependencies and blockers. Escalate delayed actions when they threaten recovery, customer service or continuity.
Step 8: Review And Close
Confirm that services are operating safely, stakeholders have received the necessary updates and the incident record is complete. Check whether temporary workarounds can be removed.
Step 9: Capture Improvements
Review what worked, where communication failed, which decisions were delayed and whether the response plan needs to change.
This approach reflects recognised incident response practice by connecting preparation, detection, response, recovery and improvement. The NIST incident response guidance provides further detail on treating incident response as part of wider organisational risk management.
How Crises Control Supports Coordinated IT Response
Crises Control can provide a coordination layer around existing monitoring, service management and security tools.
It does not need to replace technical monitoring systems. Instead, it can help organisations manage the activities that follow an alert.
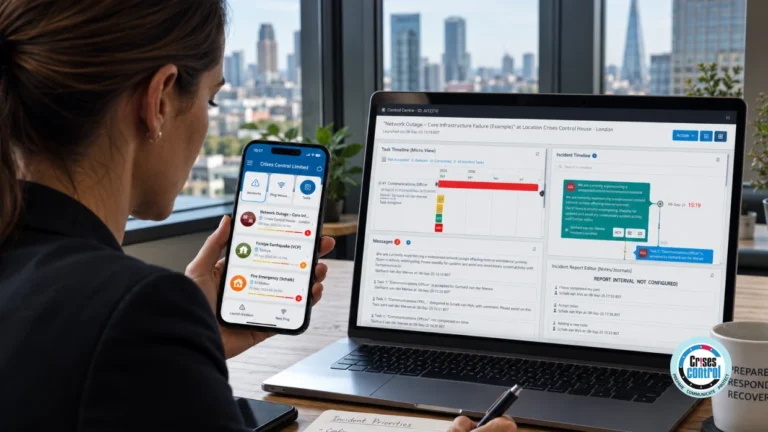
Digital response plans can establish the steps and roles required for different incidents. Role-based communication can direct information to the people who need to act, while acknowledgement tracking can help confirm that important messages have been received.
Tasks can be assigned to named owners, progress can be monitored and unresolved issues can be escalated. Cloud access can support authorised responders working from different locations, while incident records can provide a structured history of communications, actions and decisions.
This is useful when an IT incident involves more than the technical team. A network outage, cyber incident, supplier failure or major application problem may require input from service delivery, operations, communications, business continuity, legal and senior leadership.
Crises Control can sit around the existing technical response process, helping connect alerts with communication, decision-making and coordinated action. Its IT Alerting solution provides a practical example of how alerting, response plans, task assignments and escalation can work together during an incident.
For a related perspective, read Incident Management Software: Beyond The IT Team , which explores how technical incidents can affect customer service, operations, leadership and business continuity.
The Real Test Is What Happens After The Alert
An alert is useful because it draws attention to a possible problem. It does not, by itself, establish ownership, assess business impact, coordinate tasks or keep stakeholders informed.
A complete incident response process needs to connect the technical signal with the wider organisational response.
For IT leaders, the key question is not simply whether the organisation can notify an engineer when a system fails. The more useful question is whether the organisation can coordinate the people, decisions and actions required to manage the consequences.
An Incident Management Platform can help bridge that gap by connecting digital plans, role-based response, reliable communication, task ownership, escalation and incident records.
Crises Control supports this wider approach by connecting digital response plans, communication, task ownership and escalation around the technical systems already used by IT teams.
The aim is not to create another layer of technology for its own sake. It is to give teams a clearer way to move from detection to action, from action to recovery and from recovery to improvement.
Frequently Asked Questions
What Is An Incident Management Platform?
An Incident Management Platform is a digital system that helps organisations manage and coordinate incidents from initial detection through response, recovery and review. It can connect communication, task ownership, escalation, response plans and incident records.
Is IT Alerting Software The Same As Incident Management Software?
No. IT Alerting Software focuses mainly on notifying the right people about a technical issue. Incident Management Software supports the wider process, including business impact assessment, communication, task management, decision-making, escalation and recovery.
Why Do IT Teams Need Incident Coordination Software?
IT teams may need Incident Coordination Software when an incident affects several departments, customer services, suppliers or critical business activities. It helps keep information, responsibilities and actions connected while the technical investigation continues.
Can An Incident Management Platform Replace Monitoring Tools?
No. Monitoring, security and service management tools remain important for detecting and investigating technical issues. An Incident Management Platform can work alongside those systems by coordinating the people and business activities involved in the response.
What Should IT Leaders Look For In An Incident Management Platform?
IT leaders should assess whether the platform supports digital response plans, role-based communication, reliable alert delivery, acknowledgement tracking, task ownership, escalation, cloud access, incident records and post-incident review. The system should also be practical for people to use under pressure.
This article was drafted with AI assistance and reviewed by the Crises Control team. Featured image: AI-generated.